Data Platform Reference Architecture
The data platform reference architecture covers ingestion, storage, processing and consumption, with governance, security, DataOps and cloud examples.
Data Platform Component Model
Hover over components to highlight, and click any item to see capability summaries and cloud vendor services.
From architecture to patterns
These components have a pattern in the library that shows how they are built and where they fit.
| Component | Patterns |
|---|---|
| Data Queries | |
| Data Visualization | |
| Model Serving & Advanced Analytics | |
| Data APIs | |
| Stream Processing | |
| Data Lake | |
| Enterprise Data Warehouse (EDW) | |
| Purpose-Built Databases | |
| Vector Store | |
| Stream & Messaging Ingestion | |
| API Ingestion | |
| Data Masking & Encryption | |
| Master & Reference Data Management |
Overview
A data platform is a governed, shared foundation that acquires data from operational systems, applications, files and event streams, lands it once, processes it, and serves it to analytical and decision-support workloads. It supports reporting and analytics, operational analytics, and machine learning and AI from one governed source of data.
This reference architecture specifies the components, what each is responsible for, and the relationships between them. It also defines the governance, security and operational controls that apply across all components. The architecture is vendor-neutral. Each capability is mapped to example services on AWS, Azure and Google Cloud and linked to the implementation patterns that realise it.
Scope
In scope. The platform is responsible for:
- Acquisition. Ingesting data from source systems through the integration patterns.
- Governance and security. Cataloguing, quality, lineage, access control and protection of data across its lifecycle.
- Storage and processing. Retaining, transforming and curating data for analytical use.
- Serving. Publishing data products, features, models and scores to consumers and decision systems.
Out of scope.
- Not an integration platform. Moving business transactions between operational systems is the responsibility of the Enterprise Integration Platform reference architecture and the integration patterns. The data platform receives data from, and publishes data back through, those patterns. It does not replace them.
- Not an application stack. Operational applications own their transactional databases. Platform stores support analytical, reporting and decision workloads only. An application that needs its own database has one in its own architecture, fed from the platform.
- Not only a reporting warehouse. Reporting is one consumer of platform data, alongside models, operational analytics, and data published through APIs and event streams.
Why the data goes in
| Timescale | Typical decision | What the platform supplies |
|---|---|---|
| Strategic (months) | Where to add capacity, which contracts to renew | Governed history and reporting |
| Tactical (days) | Staffing for next week, which claims to review | Forecasts, trained models and data marts |
| Operational (seconds to minutes) | Which route to take, whether to approve a payment | Features and scores, published to the system that makes the decision |
In every case the platform informs the decision and an operational system acts on it.
How data gets in and out
Data reaches the platform, and leaves it, through integration patterns. Each integration pattern comes in three versions, one for each boundary the data crosses: cloud, external and internal. The Enterprise Integration Platform reference architecture shows how they fit together, and the integration patterns library lists them all.
Data in
| Pattern | Cloud | External | Internal |
|---|---|---|---|
| Change data capture | cloud | external | internal |
| Event streaming | cloud | external | internal |
| Secure file transfer | cloud | external | internal |
Webhooks have a single pattern and no boundary versions: Webhooks (Event-Push Ingestion).
Data out
| Pattern | Cloud | External | Internal |
|---|---|---|---|
| API management | cloud | external | internal |
| Event streaming | cloud | external | internal |
| Master data management, publishing changes back to source systems | cloud | external | internal |
Processing and serving inside the platform
- Medallion Architecture
- Unified Batch & Stream Processing (Kappa)
- Open Table Format
- Data Mart
- Materialized Views
- GraphQL Data API
- Retrieval-Augmented Generation (RAG)
Component Model Layers
1. Data Sources Layer
This foundational layer represents the diverse origins of data that exist before entering the platform. These sources generate the raw information that feeds the enterprise.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Operational Databases | Core transactional relational and document engines backing the primary operational products of the enterprise. | Amazon RDS / Aurora (AWS); Azure SQL / PostgreSQL (Azure); Cloud SQL / Cloud Spanner (GCP); PostgreSQL, MySQL, MongoDB (Open Source / Other) |
| Applications | Business enterprise software suites, cloud SaaS applications, CRM, ERP, and general line-of-business software platforms. | SAP on AWS (AWS); SAP on Azure (Azure); SAP on Google Cloud (GCP); Odoo, ERPNext (Open Source / Other) |
| Streams | Unbounded telemetry feeds, clickstream trails, and internet-connected devices transmitting active continuous sensor measurements. | AWS IoT Core (AWS); Azure IoT Hub (Azure); Pub/Sub with a partner IoT platform (e.g. ClearBlade) (GCP); Eclipse Mosquitto, EMQX (Open Source / Other) |
| Structured Data | Highly structured and tabular data formatted files sent by internal teams or external vendors (such as monthly CSV summaries). | Amazon S3 Uploads (AWS); Blob Storage Inbound (Azure); GCS Bucket Uploads (GCP); SFTP, Samba (Open Source / Other) |
| Unstructured Data | Binary, heavy, and media files containing rich operational data lacking pre-defined relational structures (e.g. PDFs, images). | Amazon S3 Object Store (AWS); Azure Blob Storage (Azure); Google Cloud Storage (GCP); MinIO Object Storage (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
2. Infrastructure Layer
The underlying physical or virtualized hardware and cloud services that host the data platform. This layer provides the foundational compute, storage, and networking capabilities on which all other layers depend.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Cloud Infrastructure | Primary scalable virtual machines, bare metal components, and block storage platforms serving as the core host of the platform. | Amazon EC2 & EBS (AWS); Azure VMs & Managed Disk (Azure); Compute Engine & Persistent Disk (GCP); OpenStack (Open Source / Other) |
| Container Orchestration | Schedules, scales, and manages containerized applications and transformation tasks consistently across hybrid environments. | Amazon EKS (AWS); Azure Kubernetes Service (AKS) (Azure); Google Kubernetes Engine (GKE) (GCP); Kubernetes, Nomad (Open Source / Other) |
| Private Networking | Ensures isolation of cloud workloads using virtual firewalls, private end-points, and secure virtual private tunnels to block exfiltration. | AWS VPC & PrivateLink (AWS); Azure Virtual Network & Private Link (Azure); Google Cloud VPC & PSC (GCP); Cilium, Calico (Open Source / Other) |
| On-Premises / Hybrid | Secure on-premises physical data centres linked via high-speed dedicated tunnels for low-latency or strict data residency systems. | AWS Outposts / Direct Connect (AWS); Azure Local / ExpressRoute (Azure); Google Distributed Cloud / Interconnect (GCP); VMware, Nutanix (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
3. Data Ingestion Layer
This layer extracts data from diverse source systems, acting as the primary consumer of the Enterprise Integration Platform for event-driven and API-based feeds. Note on Data Contracts: Across all ingestion methods, this layer acts as the enforcement point for Data Contracts—ensuring incoming data adheres to agreed-upon schemas and SLAs before it enters the platform.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Database Ingestion | Safely reads transactional logs in real-time (Change Data Capture) or executes batches without impacting database performance. | AWS Database Migration Service (AWS); Azure Database Migration Service (Azure); Google Datastream (GCP); Debezium, Fivetran, Airbyte (Open Source / Other) |
| Stream & Messaging Ingestion | Directly ingests, aggregates, and pipes high-velocity messaging topics and streaming data sources straight into storage. | Amazon Kinesis Data Streams (AWS); Azure Event Hubs (Azure); Google Pub/Sub (GCP); Apache Kafka, Logstash (Open Source / Other) |
| API Ingestion | Connects securely to third-party SaaS tools and web endpoints to pull or push data assets via REST/GraphQL or webhooks. | Amazon AppFlow (AWS); Azure Logic Apps (Azure); Google Cloud Data Fusion (GCP); Meltano, Singer (Open Source / Other) |
| File Ingestion | Managed secure data transfer services to safely receive, move, and store external file exports, flat archives, and XMLs. | AWS Transfer Family (AWS); Azure Data Factory (Azure); GCP Storage Transfer (GCP); rclone, Apache NiFi (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
4. Data Storage Layer
This layer provides scalable, decoupled storage for all data types. It supports everything from raw object storage to highly structured analytical models and specialized operational formats.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Data Lake | Highly cost-effective object storage holding all historical records. Modern architectures overlay open table formats (Iceberg, Delta) for ACID reliability. | Amazon S3 + Apache Iceberg (AWS); ADLS Gen2 + Delta Lake (Azure); Google Cloud Storage + Iceberg (GCP); MinIO + Apache Iceberg (Open Source / Other) |
| Enterprise Data Warehouse (EDW) | Structured analytical relational storage optimized for complex reporting queries, running highly performant mass analytical schemas. | Amazon Redshift (AWS); Azure Synapse / Fabric (Azure); Google BigQuery (GCP); Snowflake, ClickHouse (Open Source / Other) |
| Streaming Broker | Distributed, immutable commit log with configurable retention (Kafka-style) that durably stores high-velocity event streams, enabling replay, decoupled consumers, and multi-subscriber fan-out. | Amazon MSK (AWS); Azure Event Hubs (Azure); Google Pub/Sub (GCP); Apache Kafka, Redpanda (Open Source / Other) |
| Purpose-Built Databases | Specialized non-relational database services optimized for document, graph, key-value, or low-latency lookup needs. These stores serve analytical and decision workloads, and applications keep their own databases. | Amazon Neptune / DocumentDB (AWS); Azure Cosmos DB (Azure); Google Firestore / Spanner (GCP); MongoDB, Neo4j, PostgreSQL (Open Source / Other) |
| Vector Store | Specialized databases designed to store, index, and query high-dimensional vector embeddings—crucial for modern semantic search, RAG, and generative AI pipelines. | Amazon OpenSearch / RDS pgvector (AWS); Azure Cosmos DB (Vector Search) / AI Search (Azure); Vector Search / Cloud SQL pgvector (GCP); pgvector, Qdrant, Milvus, Chroma (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
5. Data Processing Layer
This layer encompasses the compute engines responsible for transforming, cleaning, enriching, and modeling the data. It also includes the heavy computational lifting required for artificial intelligence.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Distributed Batch Processing | Scalable parallel compute clusters executing scheduled transformations on vast historical datasets. | Amazon EMR, AWS Glue (AWS); Azure Databricks, Synapse Spark (Azure); Google Managed Service for Apache Spark (GCP); Apache Spark, dbt (Open Source / Other) |
| Stream Processing | Real-time stream computations transforming unbounded data flows instantly for alerting and rapid-response dashboarding. | Amazon Managed Service for Apache Flink (AWS); Azure Stream Analytics (Azure); Google Dataflow (GCP); Apache Flink, Spark Streaming (Open Source / Other) |
| ML Model Training | High-performance GPU-backed compute used to develop, train, evaluate, and version machine learning and deep learning models — distinct from inference, which is served via the Consumption layer. | Amazon SageMaker (AWS); Azure Machine Learning (Azure); Agent Platform Managed Training (GCP); Kubeflow, PyTorch (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
6. Data Consumption Layer
This layer exposes the processed data and trained models to the end consumers. Note on Data Contracts: Interfaces exposed here (like APIs and outbound feeds) are governed by outbound Data Contracts, guaranteeing reliability for downstream consumers.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Data Queries | Ad-hoc, federated SQL query engines that allow interactive querying directly on the data lake without moving it to a warehouse. | Amazon Athena (AWS); Synapse Serverless (Azure); BigQuery (External) (GCP); Trino, Presto (Open Source / Other) |
| Semantic / Metrics Layer | One definition of each business metric, used by dashboards, models and AI agents. | Metric definitions held in a BI model or a standalone semantic service |
| Data Visualization | Business Intelligence tools used to construct dynamic, interactive dashboards and scheduled, paginated reports. | Amazon Quick Sight (AWS); Microsoft Power BI (Azure); Google Looker / Data Studio (GCP); Apache Superset, Metabase (Open Source / Other) |
| Model Serving & Advanced Analytics | Hosted, highly scalable inference endpoints serving low-latency predictions and generative model results to client systems, alongside complex statistical analysis and exploratory data science workloads. | SageMaker Endpoints (AWS); Azure ML Endpoints (Azure); Agent Platform Endpoints (GCP); BentoML, KServe (Open Source / Other) |
| Data Activation / Reverse ETL | Pushes curated analytical profiles (e.g. customer churn risk scores) back to operational business applications through integration patterns, so the system that acts on the decision receives it. | Amazon AppFlow (AWS); Azure Data Factory (Azure); BigQuery EXPORT DATA (Pub/Sub, Spanner, Bigtable) (GCP); Hightouch, Census (Open Source / Other) |
| Operational Data Stores (ODS) | Read-optimized serving stores that cache curated, pre-aggregated data products for low-latency retrieval by the operational systems that act on a decision, bridging the analytical platform and those systems. These stores serve analytical and decision workloads, and applications keep their own databases. | Amazon DynamoDB / ElastiCache (AWS); Azure Managed Redis (Azure); Google Cloud Bigtable (GCP); Apache Cassandra, Redis (Open Source / Other) |
| Data APIs | Exposes secure GraphQL or REST APIs on top of data warehouses or operational caches to grant programmatic access to application developers. | Amazon API Gateway (AWS); Azure API Management (Azure); Google Apigee (GCP); Hasura, PostgREST (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
7. Data Consumers Layer
The topmost layer, representing the end-users and systems that derive business value from the data platform.
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Business Users | Analysts, executives, and operational business staff relying on visual dashboards, metrics, and BI reports for daily strategic decisions. | Amazon Quick Sight (AWS); Microsoft Power BI (Azure); Google Looker / Data Studio (GCP); Apache Superset (Open Source / Other) |
| Data Scientists | Power users building machine learning models, conducting advanced predictive analytics, and running exploratory data experiments. | SageMaker Notebooks (AWS); Azure ML Studio (Azure); Agent Platform Workbench (GCP); JupyterHub, MLflow (Open Source / Other) |
| Applications | Internal or custom line-of-business applications consuming operational or analytical data products to drive workflows. | Operational systems (receive data through integration patterns) |
| External 3rd Parties | Third-party clients, external vendors, or industry partners consuming platform data safely via secure outbound B2B feeds or API gateways. | AWS Data Exchange (AWS); Azure Data Share (Azure); Analytics Hub (GCP); Delta Sharing (Open Source / Other) |
| Automated Systems | Autonomous systems, enterprise robotic process automation (RPA), and automated algorithms consuming insights with no human in the loop. | AWS Step Functions (AWS); Azure Logic Apps (Azure); GCP Workflows (GCP); Node-RED, temporal.io (Open Source / Other) |
| Technical Operations | Data engineers, platform support teams, and SRE professionals monitoring pipeline stability, data quality alerts, and costs. | AWS CloudWatch (AWS); Azure Monitor (Azure); Google Cloud Observability (GCP); Grafana, Prometheus (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
Integration carries data in and out of the platform
Data reaches the platform through integration patterns, and results leave it the same way. The platform lands the data once and governs it. Integration moves it in and out.
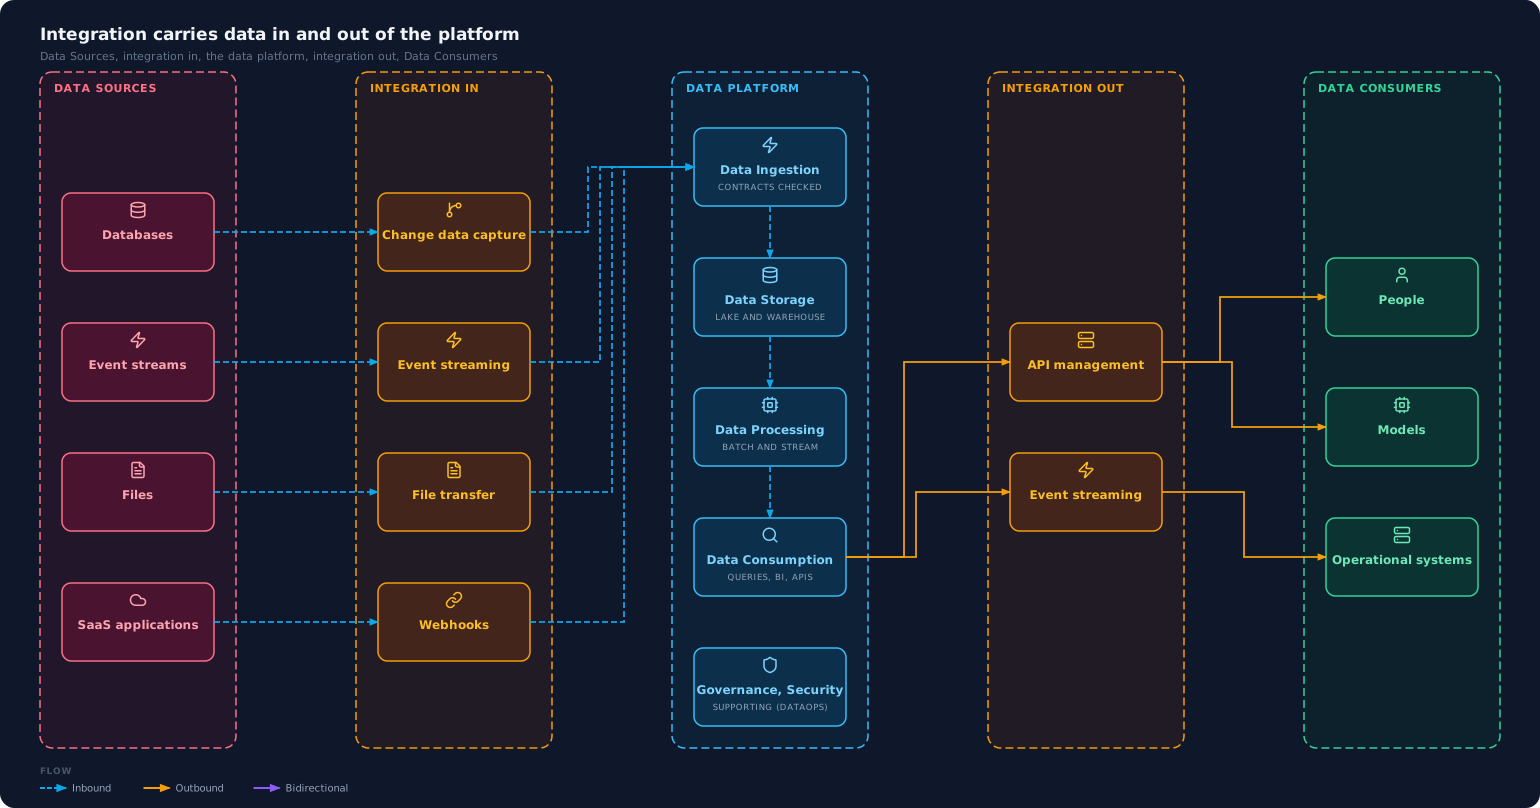
The diagram is wide, so open it at full size to read the labels.
Cross-Cutting Layers
These layers span horizontally across the platform, ensuring data remains secure, compliant, understandable, and operations run smoothly.
Data Governance Layer
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Data Discovery & Metadata | A searchable database of data schemas, terminology definitions, and ratings allowing users to find data fast. | AWS Glue Data Catalog (AWS); Microsoft Purview (Azure); Google Knowledge Catalog (GCP); Amundsen, DataHub, Apache Atlas (Open Source / Other) |
| Data Quality | Continuously asserts quality parameters (freshness, completeness, shape) on active pipelines and alerts on deviation. | AWS Glue Data Quality (AWS); Purview Data Quality (Azure); Google Knowledge Catalog (auto data quality) (GCP); Great Expectations, Soda, Deequ (Open Source / Other) |
| Data Lineage | Draws visual execution pathways of data from original source, through processing transformations, to visualization dashboards. | Amazon SageMaker Catalog (data lineage) (AWS); Microsoft Purview Lineage (Azure); Google Knowledge Catalog (data lineage) (GCP); OpenLineage, DataHub (Open Source / Other) |
| Master & Reference Data Management | Reconciles and creates a single golden master record for core business entities (like 'Customer' or 'Product'). | AWS Entity Resolution / partner MDM (AWS); Profisee on Azure (Azure); Partner MDM (e.g. Reltio, Semarchy) (GCP); TIBCO EBX, Talend MDM (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
Data Security Layer
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Access Control | Enforces row-level, column-level, or cell-level access constraints on queries depending on corporate role clearance. | AWS Lake Formation, IAM (AWS); Microsoft Purview Access (Azure); BigQuery Policy Tags, IAM (GCP); Apache Ranger, Immuta (Open Source / Other) |
| Data Masking & Encryption | Obfuscates sensitive parameters like credit card numbers dynamically and encrypts data both in transit and at rest. | AWS KMS, Redshift Masking (AWS); Azure Key Vault, SQL Masking (Azure); Google Cloud KMS, Sensitive Data Protection (GCP); HashiCorp Vault, Apache Ranger (Open Source / Other) |
| Secrets Management | Central repository holding, rotating, and tracking programmatic access credentials and server connection strings safely. | AWS Secrets Manager (AWS); Azure Key Vault Secrets (Azure); Google Secret Manager (GCP); HashiCorp Vault (Open Source / Other) |
| Data Classification & Sensitive Data Discovery | Scans new data objects to identify and tag PII (Personally Identifiable Information), health tags, or banking numbers. | Amazon Macie (AWS); Microsoft Purview Information Protection (Azure); Google Cloud Sensitive Data Protection (GCP); Apache Ranger Classification (Open Source / Other) |
| Audit Logging | Tamper-evident system capture documenting every single query, configuration alteration, and file download action. | AWS CloudTrail (AWS); Azure Monitor Logs (Azure); Google Cloud Audit Logs (GCP); Elasticsearch, OpenSearch (Open Source / Other) |
| Identity & Access Management (IAM) | Federates user profiles, handles identity authentication, and issues safe machine credential tokens to control who and what can access platform resources. | AWS IAM & Identity Center (AWS); Microsoft Entra ID (Azure); Google Cloud IAM (GCP); Keycloak, Okta (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
Supporting Services (DataOps) Layer
| COMPONENT | DESCRIPTION | EXAMPLES |
|---|---|---|
| Data Orchestration & Workflow Management | Pipes execution dependency commands across tasks, ensuring batches complete sequentially and retry on failure. | Amazon MWAA (Airflow) (AWS); Azure Data Factory (Azure); Google Managed Service for Apache Airflow (GCP); Apache Airflow, Prefect, Dagster (Open Source / Other) |
| Monitoring & Observability (incl. FinOps) | Tracks resource workloads, queries execution cost metrics, system crashes, and platform performance latency in real-time. | Amazon CloudWatch & Cost Explorer (AWS); Azure Monitor & Cost Management (Azure); Google Cloud Observability & FinOps (GCP); Grafana, Prometheus, Datadog (Open Source / Other) |
| CI/CD & Source Control | Automates testing code integrations, model versioning, and environment container migrations directly from Git. | AWS CodePipeline (AWS); Azure Pipelines (Azure); Google Cloud Build (GCP); GitHub Actions, GitLab CI (Open Source / Other) |
| Infrastructure as Code (IaC) | Represents data warehouses and infrastructure configurations as code structures, allowing rapid environment duplication. | AWS CloudFormation (AWS); Azure Bicep (Azure); GCP Infrastructure Manager (Terraform) (GCP); Terraform, OpenTofu, Pulumi (Open Source / Other) |
| Data Modeling Tools | Visual and programmatic systems to map relational schemas, relational keys, warehouse stars, and data vault architectures. | AWS Glue Schema Registry (AWS); Synapse Database Designer (Azure); Dataform (GCP); dbdiagram.io, SqlDBM, Erwin (Open Source / Other) |
Products are listed as examples to show how a component can be implemented. Inclusion is not an endorsement of the vendor, and omission is not a judgement about the product.
Examples
Four examples show data informing a decision that a person or an operational system then acts on. They are not equally well sourced, so each one says what kind of source it rests on.
Illustrative Scenario
A hypothetical scenario showing how the pattern applies. Not a client case study.
Logistics routing. Flooding closes the main route of a regional freight carrier. Traffic and weather feeds, depot records and shipment data already sit in the platform, and a delay model has been trained on past disruptions. Within minutes the model estimates that one alternative route adds about an hour to a delivery and another adds about five hours. The platform publishes those estimates, with the shipments each one affects, to the routing system. The routing system weighs them against delivery windows and vehicle availability, chooses a route, and tells the drivers. The platform does not reroute anything. A dispatcher can still override the choice, and the platform has no say in that either. Afterwards the actual delays go back into the platform, so the estimates can be compared with what happened and the model can be checked and retrained. The decision about the route stays with the operational system and the people who run it. The platform's part is to have the data ready, to turn it into estimates quickly, and to keep a record of what it published and what followed.
Benefit fraud screening: third-party reporting
Sources: the National Audit Office report of 22 October 2025, which is the primary source, and The Register's report of 27 October 2025 on it.
The NAO reports that, since May 2022, the UK Department for Work and Pensions has used a machine learning model to flag potentially fraudulent Universal Credit advance claims. The model refers the claims it assesses as high risk to a caseworker, and department staff, not the model, decide whether the advance is paid. The NAO reports the department's estimate that the model saved about £4.4 million from 2022-23 to 2024-25. It also reports fairness findings: the department's published analysis showed older claimants and non-UK nationals being referred for review more often than expected, and the department could analyse only one of the nine protected characteristics (age) because it had limited data. The NAO adds that the department's IT systems are not fully integrated and that a lack of common data standards makes fraud and error harder to identify, and The Register reports that this limits how far the work can scale. The sources do not describe the department's data architecture, so the example shows the decision pattern, not a platform design.
Card fraud scoring: vendor reference design
Source: a Databricks engineering blog post, 19 May 2026. It is the vendor's own design for a reference implementation, not a customer case.
In the design, card transactions arrive as a stream. The pipeline computes features for each card, such as how many transactions it made in the last minute, and keeps them in a separate low-latency store. A model scores each transaction, the score routes it as approved, flagged for review, or blocked, and the decision is published to topics that downstream systems act on. The example shows the split this page describes: the platform computes the features and trains the model, and a store built for fast reads lets the decision be made at speed.
Utility storm planning: vendor blog, self-reported
Source: a Databricks blog post, 18 February 2025, about Alabama Power's use of the platform. It is the vendor's own account, with comments from the utility's staff.
According to the post, Alabama Power, working with the consultancy E Source, built two applications on Databricks. One forecasts how severe weather will affect its grid, including the number of incidents, the resources needed and the estimated time to restore supply, to help its storm centre plan. The other monitors reliability, so that underperforming equipment can be maintained or replaced. The post also gives savings estimates. They are projections, so this page does not repeat them.
Use and cite this
Free to use and adapt under CC BY 4.0. Credit: David Tirabassi, IT Architecture Patterns.
Attribution: Source: David Tirabassi, IT Architecture Patterns (https://www.itarchitecturepatterns.net/reference-architectures/data-platform-reference-architecture), licensed under CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/).